SQL DISTINCT: remove duplicate rows
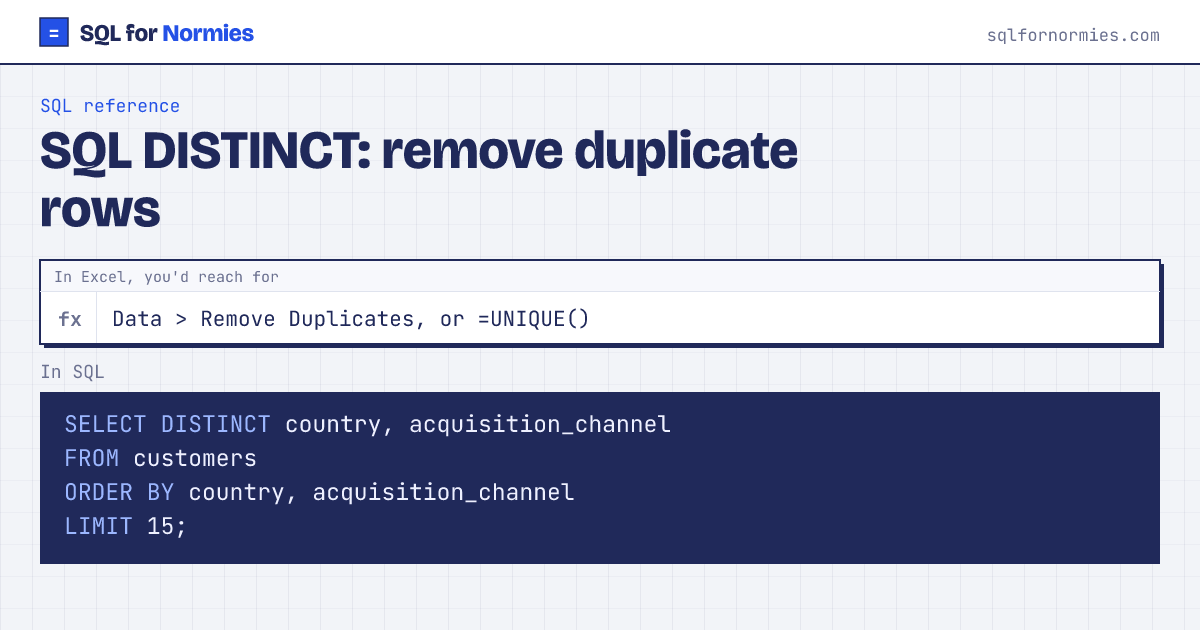
SELECT DISTINCT shows each different row once. With one column it's a unique list; with several it's every unique combination. Nothing is deleted from the table, which makes it safer than Excel's Remove Duplicates.
Syntax
SELECT DISTINCT col_1, col_2
FROM table;
Try itEdit the query, then Run
| country | acquisition_channel |
|---|---|
| Australia | organic_search |
| Australia | paid_search |
| Australia | partner |
| Australia | referral |
| Australia | social |
| Brazil | organic_search |
| Brazil | paid_search |
| Brazil | partner |
| Brazil | referral |
| Brazil | social |
Showing 10 of 15 rows. Press Run to see them all.
To actually find the duplicates (which emails appear twice?), group and count instead: SELECT email, COUNT(*) FROM customers GROUP BY email HAVING COUNT(*) > 1.
Your turn
List every different plan and mrr combination in subscriptions, cheapest first.
SELECT DISTINCT plan, mrr ... ORDER BY mrr.
This page on one card